Creating original content takes a lot of time, money, and expertise. Data brokers and large language model creators often scrape public web pages at scale to train their models, sometimes without attribution or compensation. If your articles, product descriptions, or research give you a competitive edge, it’s reasonable to ask how to limit unauthorized use.
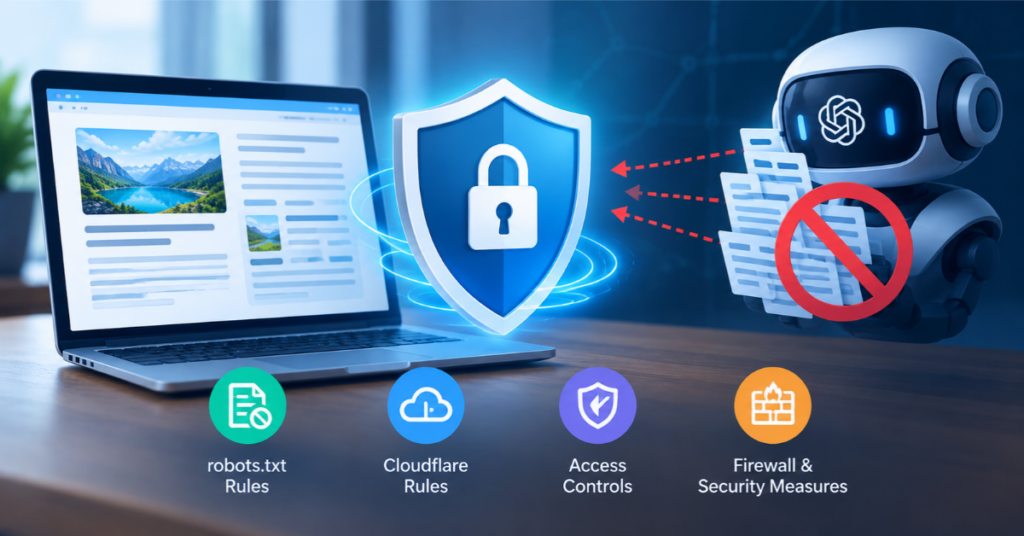
No method is foolproof, but a layered approach can greatly reduce exposure. Here are the major layers.
Begin With Clear Signals
The easiest control is robots.txt Many major AI crawlers name their user agent and many honor disallow rules. You can block certain agents and still allow search bots to be left alone. Add meta robots’ directives or appropriate opt-out headers where applicable. These signals are voluntary, so think of them as a first line, not the only line.
Update your website terms to clarify that you require written permission to collect automated data for model training. This gives you legal footing should you need to make a complaint later.
Enforce at the Edge of the Server
Polite bots follow rules; impolite bots ignore them. Use a web application firewall or CDN to rate limit rapid requests, challenge suspicious clients and block IP ranges and data center networks known for scraping. Behavior is a big clue: a client fetching hundreds of pages a minute, one after the other, is rarely a human reader.
When you search for SEO services in Indore, remember that rules of protection must be tested so that legitimate search crawlers can still get access while unwanted collectors are turned away.
Indirectly protects rankings (content protection). SEO services in Indore are increasingly monitoring for duplicate or republished content, as scraped copies hosted on stronger domains can outrank the originals.
Make scraping harder and less worthwhile
- Put premium content behind paywall or login.
- Show the preview only to anonymous users and load the rest after authentication.
- If copied later, mark it with unique phrasing or subtle watermarks.
- Stuff a few articles with some canary text or tracking phrases and see if they show up in the AI outputs.
- Do not publish full content through open APIs and feeds.
Misuse Monitor
Search for original phrases from your content in quotation marks. Create alerts for your brand and unique phrases. Look for unusual spikes in server logs and unknown user agents. If you see blatant copying, get the evidence and file a takedown or removal request with the host or publisher.
Protect & Be Seen
There is a tradeoff. Blocking all artificial intelligence systems might lower the likelihood of your content being cited in AI-generated answers, which can boost brand awareness. Many publishers have struck a middle ground. They let assistants link back to their sources, block pure training crawlers and keep premium content gated.
A thoughtful digital marketing services provider in Indore can help you determine where that line sits for your industry, audience and revenue model.
Protection is most effective when it supports broader goals. Digital marketing services providers can sync scraping controls to email, social and paid campaigns, so protected material still reaches the right audience.
Takeaway
Content protection is a continuous process. Use clear signals. Use strong technical controls. Use legal terms and monitoring. Adapt to new crawlers.
Tags:
Founder of Neha SEO Solutions, Indore. Neha has handled SEO and digital marketing projects for clients across India, the USA, UK, Canada, Australia and New Zealand.
About Neha SEO Solutions →